Anamap Blog
Product Data Interview: Swetha Selvanayagam
Interviews
Updated 2026-11-03

This is part of our Product Data Interviews series, where we ask product managers across the industry the same set of questions about how they use data, what slows them down, and what helps them make better product decisions.
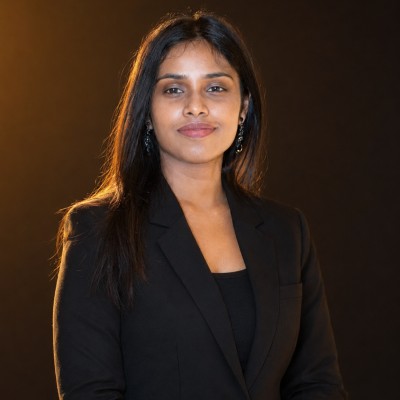
Swetha Selvanayagam is an AI product manager leading a headless initiative to make software usable through APIs and developer tools, both by AI agents and by people who prefer to work programmatically. Her decisions span which capabilities to expose first, how tools should behave when agents act on someone's behalf, and how these products are packaged and launched.
In this interview, Swetha explains how customer workshops and usage data led her to prioritize safety, approvals, and traceability over a longer feature list. She also discusses why missing data should be neutral, how agents complicate the definition of usage, and why self-serve access needs documentation as well as query tools.
Connect with Swetha on LinkedIn.
1. What kind of product decisions are you personally responsible for?
In my current role, I lead a headless initiative. Most software, ours included, was built on the assumption that a person would use it through a UI. That assumption is changing quickly. AI agents are now doing a lot of the work users used to do by hand, and agents don't click through screens. They need everything to be available through APIs and the developer tools built on top of them.
So my job is to make the product fully usable without the UI, both by agents and by users who simply prefer to work programmatically. The decisions I own are mostly about which capabilities we expose first and through which tools, how those tools should behave safely when an agent is acting on someone's behalf. I also work on how these agentic products are packaged and launched.
What I find interesting is that the definition of a user has changed. For an agent, the question isn't whether a screen is intuitive. It's whether the agent can find the right capability, call it correctly, and leave behind a record that a person can trust.
2. When you're evaluating whether something is working (or worth building), what signals matter most to you?
I usually look at three things.
First, where the industry is going. Some shifts are bigger than any one roadmap, and software being used by agents rather than people is one of them. When most of the market is moving in one direction, choosing not to move is still a decision, and usually an expensive one.
Second, company priorities. Every company has a few bets it's making, and I want to know whether what I'm building supports those bets or is a one-off. Work that supports the main strategy tends to compound over time.
Third, what users are actually telling us. This is the most specific signal. A user tries to do something programmatically, finds it isn't supported, and asks for it. Or an early adopter shows us exactly where a workflow broke.
These three don't always agree, and most of the judgement is in balancing them. A request from one large customer can be very loud, and it's tempting to just fix it. I try to separate how loudly something is asked for from how widely it's needed.
3. Walk me through a recent product decision you made that involved data. What did the process actually look like?
A good example is deciding what to build next for a set of agent tools. I approached it from both the qualitative and the quantitative side, because neither was enough on its own.
On the qualitative side, I did one-on-one interviews and also ran in-person research workshops, with 20 to 25 users in a room. I made the workshops fairly game-like. People stack-ranked their problems, made trade-offs about what they'd want solved first, and put together the workflow they'd ideally want. I've found that if you ask users directly, they often can't tell you what they need. If you put them in a situation where they have to choose, their real priorities come out. After the activities, I asked direct questions to understand the reasons behind their choices.
On the quantitative side, I looked at which capabilities were used most and by how many accounts, what users of our tools were asking for, which tools were being called, where errors were happening, where people dropped off during setup, and how usage split between reading, writing and deleting data. That last one mattered a lot. How comfortable people are letting an agent delete something tells you whether to invest more in write actions or stay focused on read-only use cases for now.
I combined all of this into a weighted score. Direct customer evidence had the most weight. In the end, the research shaped the outcome more than the numbers. The biggest blockers weren't missing features. They were about trust: safety, approvals, and being able to trace every action back to a person. So I kept the build list short and prioritised guardrails for agentic activities over breadth.
4. How confident do you generally feel in the data available to you when making product decisions? What tends to increase or reduce that confidence?
It depends a lot on the source. Working closely with APIs makes this harder than it sounds, because API-level data is very high volume and expensive to query, and it's usually less complete than people assume.
I've run into situations where a processing step in a logging pipeline altered some records, so things that were clearly being used didn't show up as used at all. I've also seen data where a blank field could mean either lack of usage (or) missing data.
Because of that, I don't treat any one source as the truth. I combine several, give each an explicit weight, and keep all the inputs visible so anyone can question the weighting. I also try to follow one rule: missing data should be neutral, not negative. Usage can raise the priority of something, but a lack of usage data shouldn't lower it.
This matters more in products with many parts that depend on each other. Something can look minor on its own and turn out to be important because other parts rely on it, so you have to look at data together rather than in isolation.
My confidence goes up when different sources point to the same conclusion. It goes down when data is missing or when I can't trace a number back to where it came from.
5. What's the most frustrating or time-consuming part of getting the insights you need to make a decision?
Most products aren't built with measurement in mind from day one. Someone realises later that they need a certain metric, and by then adding the instrumentation is harder, and the history before that point is simply gone.
Even when data does exist, it's rarely well labelled. Which table holds what, and what a field actually means, often lives in one person's head rather than anywhere written down. So a lot of time goes into finding the right person and asking.
Then there's the pipeline. It's quite common to write the requirements for a dashboard well in advance and still find out late that the data can't flow the way everyone assumed. Fixing that usually involves several teams, each with their own priorities, so it takes time.
None of these are hard problems on their own, but together they can cost weeks. Most of them would be avoided by writing a short data definition at the same time as the product spec, which is why I now treat instrumentation as part of the product.
6. How self-serve is data access for product managers at your company today?
Getting access is usually the easy part. In most places I've worked, a PM can get into the data warehouse and logging tools without much trouble. What isn't self-serve is understanding what you're looking at.
I can usually query a table. But do I know how complete it is, how fresh it is, whether an empty value means zero or "not tracked", or which of two similar tables is the right one? Usually not without asking someone. So on paper it's self-serve, but anything beyond an existing dashboard tends to need help from a data team, and those teams are almost always stretched.
AI has made writing queries much easier, which is great. But it has moved the bottleneck rather than removed it. A model will write a query against a table it doesn't understand just as confidently as against one it does. Without clear definitions, you just get to a wrong answer faster.
For me, real self-serve comes down to a few basic things: documentation that comes with every new dataset, a clear owner for each one, and metric definitions written down where people actually use them.
7. What's the hardest thing about turning data into action rather than just more dashboards or reports?
A dashboard tells you what happened. Taking action needs a case for what will happen if you do something, and that's much harder to make.
When I want to act on something I've found, I need to be able to answer a few questions. Which metric will this move, roughly by how much, and over what period? Do I have enough data to back that up, or am I working from one conversation or one short spike? And is this worth more than the other things the same team could be working on?
The other difficulty is that the same data can tell different stories depending on who's looking at it. Say a large share of users start a setup flow and don't finish it. One team might say the flow needs to be simpler. Another might say those users never needed this solution. The data alone doesn't settle it. Context does: who is dropping off, what they were trying to do, and what it costs when they leave.
So the real work isn't making the chart. It's writing down the hypothesis, the metric you expect to move and the outcome you expect before you build, and then checking afterwards. Without that step, you often end up with a dashboard everyone finds interesting and nobody acts on.
8. Are there product metrics or definitions that people at the company regularly interpret differently?
"Usage" is the one I see interpreted differently most often.
Different people mean different things by it. It can mean the number of API calls, the number of accounts or the number of active users, and these can tell very different stories. A single automated job can generate more API calls in a day than thousands of people do in a month. So something can look heavily used by one measure and barely used by another. When I'm prioritising, I lean towards the number of customer accounts, because it shows how widely something is needed rather than how much noise it makes.
Agents make this harder, because it's no longer obvious who the user is. If one person sets up several agents, is that one user or several? Different teams answer this differently.
There's also a bigger question underneath. Because agent access is such new territory, it's hard to know whether what people do today really reflects what they'll want.
Historical data tells you what people did with software built for humans. It can't tell you what agents will need. The features humans rarely touch might be the ones agents can't live without, and the ones humans used every day might quietly stop mattering.
So I treat past usage as a starting point rather than a prediction, and I compare it with what early adopters are actually trying to do with agents.
9. What's a surprising or overlooked source of product insight that you think more teams should pay attention to?
Failures and workarounds. Most teams focus on what's working, like successful calls, completed flows and adopted features. I've often learned more from what people try to do and can't.
Error logs are a good example. A failed request isn't only a reliability issue. It also tells you what someone was trying to do. If people keep trying to do something that doesn't exist, that's a demand nobody has formally requested.
Workarounds are similar. When customers write their own scripts to get around a gap in your product, they've basically written the requirement for you and spent their own time doing it. That's a very honest signal, because building a workaround costs something.
Another thing I've started paying attention to in interviews is how quickly someone answers. If I ask what's frustrating them and they have to think about it for a long time, it usually isn't really frustrating them. When something genuinely bothers people, they tell you straight away, usually with a story attached.
10. What advice would you give another PM trying to make better product decisions with data?
Three things.
First, plan your instrumentation before you launch. Write down what you'll capture, what each field means and who owns the data, at the same time as you write the spec. It doesn't take long, and fixing it after launch takes much longer. Some of the history you'll never get back.
Second, pair the numbers with conversations. Data tells you where something is happening, and users tell you why.
Third, don't wait until you have all the data before doing anything. Especially in a new area, the data you want often doesn't exist yet. Start with a reasonable hypothesis, be clear about what you expect to happen, try something small and learn from it. More data will come once you start. And if the experiment fails, that's still useful, because it tells you which assumption was wrong and gives you something concrete to work with next.